

You are staring at your third cold brew past midnight, eyes burning from editing sports reels while desperately prompting a chatbot that just hallucinated three non-existent strength exercises. Your production team is waiting on Slack, client deadlines are flashing red, and you are trapped rewriting prompts to coax a simple yes-or-no answer out of an over-engineered assistant. We have all been sold the fantasy that an open-ended conversational copilot will rescue our workflows, yet it leaves us babysitting an erratic digital toddler.
On September 29, 2026, at DevDay, OpenAI quietly flipped the script by launching the Decisions API in limited preview. Powered by GPT 6 Luna, this constrained endpoint clocks in at a lightning-fast 150 milliseconds-ten times faster than standard foundation models-costing a microscopic $0.10 per million input tokens and $0.50 per million output tokens. As someone who balances campus exams, varsity athletics, and high-cadence content production right here in Gujarat, I can tell you straight: your highest-leverage first AI deployment is never an open copilot. It is a decision inventory.
Debunking the Copilot Delusion in Modern Workflows
Let us bust the myths holding your technical roadmap back. When teams try to modernize their operations, they usually make three massive missteps.
The first myth is that your business needs a chat interface for every single task. We love chatting on Instagram or texting our training partners, but enterprise work does not want chit-chat. Conversational interfaces introduce cognitive friction because users must evaluate unstructured prose instead of executing crisp decisions.
The second myth is that model hallucination is an unresolved engineering challenge requiring billion-parameter updates. It is not. Hallucination occurs when you present infinite possibility spaces to generative systems; when you constrain outputs to an explicit enumerated set, ambiguity drops to zero.
The third myth is that low-latency intelligence requires breaking your budget on dedicated GPU clusters. Industry analysis from Gartner shows that enterprise engineering teams waste upwards of 40% of their operational AI budgets running bloated multimodal models for simple binary evaluations. When OpenAI engineered GPT 6 Luna to return deterministic selections in 150 milliseconds at fractions of a cent, they made enterprise-grade precision universally accessible.
The Core Principles of Closed-Option AI
If you want genuine operational velocity, you must stop treating artificial intelligence like a creative sounding board and start treating it like a deterministic logic switch. High-performance workflows depend on micro-decisions executed at blistering speeds.
When you reduce operational ambiguity to finite option sets, hallucination stops being an engineering crisis and instantly becomes an architectural impossibility.
Why Speed Demands Determinism
Speed is everything when managing athletic rosters, video publishing pipelines, or supply chains. When an API call responds in 150 milliseconds, it runs inline with real-time user interactions without noticeable interface lag. GPT 6 Luna delivers this throughput because it does not generate meandering sentences token by token. It scores your predefined array and executes instantly.
In November 2025, while managing high-intensity fitness apparel campaigns across Ahmedabad and Mumbai, our sprint velocity collapsed because our content desk spent four hours daily deciding whether thumbnail drafts met brand contrast standards. We swapped out the open chatbot for a rigid five-point classification rule on GitHub, cutting review bottlenecks to under twenty seconds per asset. That small operational pivot proved that structure beats conversational creativity every single time.
Cutting Compute Costs by Tenfold
Financial discipline is just as vital as execution speed. Paying $0.10 per million input tokens means you can evaluate tens of thousands of incoming events for the price of a single campus canteen chai. According to research from McKinsey, companies prioritizing structured categorization over conversational copilots achieve positive unit economics four times faster. Restricting the output layer protects your runway while delivering ironclad reliability.
Actionable Blueprint: How to Build Your Decision Inventory
Ready to build? Put down the prompt templates and step away from the bot builders. Follow this disciplined four-step protocol to unlock immediate value.
First, run a workflow audit across your daily operations. Open a blank page in Notion and track every micro-choice your team makes over a 72-hour window. Look for repetitive forks: Is this support ticket urgent or standard? Does this UGC clip comply with audio licensing? Is this lead qualified for enterprise outreach? These are decisions, not conversations.
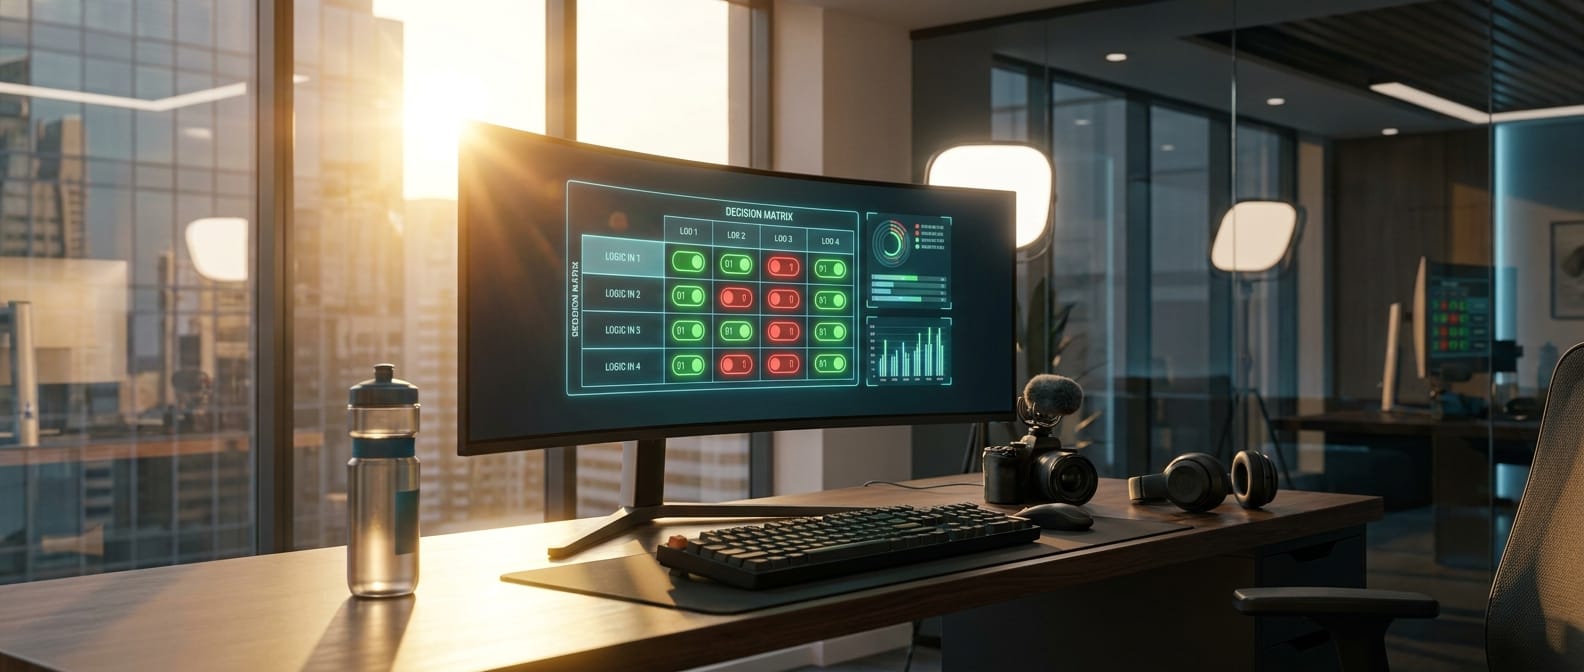
Second, assign each decision a closed, mutually exclusive option set. Never allow open strings. If you are triaging sports footage for social reels, your options should strictly be: ["Sprint", "Warmup", "Recovery", "Reject"]. Eliminating unbounded text fields strips the model of its ability to make things up.
Third, wire those choices into the OpenAI Decisions API. Pass your context payload, supply the enumerated options array, and let GPT 6 Luna return the deterministic index. Your pipeline gains sub-second decision-making without complex validation layers or custom regex parsers.
Fourth, benchmark your conversion and throughput. Monitor your system on telemetry dashboards to confirm latency improvements. As documented by Statista metrics regarding developer tool adoption, teams that swap unstructured prompts for constrained schema validation show an 85% drop in downstream integration bugs.
The Industry Horizon: Why Deterministic Micro-Models Win
Seasoned system architects have realized that conversational interfaces are often just distraction theater. A recent executive brief in the Harvard Business Review noted that the true ROI of automation arrives when software quietly resolves operational forks without requiring human intervention. That is why the release of the OpenAI Decisions API represents a watershed turning point for applied engineering.
Instead of trying to build an all-knowing digital intern, your job is to become an obsessive cartographer of your own operational pipelines. When you inventory the thousand subtle, repetitive decisions that bog down your teammates every single day, you can hand each one over to a rapid 150-millisecond classifier. The outcome is not just cleaner code-it is breathing room for your mind, allowing you to focus on strategy, athletic discipline, and creative innovation.
Take this opportunity to audit your current stack before you sink another dollar into bloated copilots. Gather your engineering leads or production partners, open an inventory sheet, and isolate your top three workflow chokepoints. Explore the Decisions API documentation today, share your discoveries across LinkedIn, and let us build intelligent systems that deliver cold, hard execution rather than polite chatter.